Arvin Zargaran / Toronto

Toronto, Canada

Software that refuses to guess.

I’m a Computer Science student at York University. Three systems on this page so far — a full-stack advising platform, a forecasting model, and a small Java application I wrote to learn where object boundaries belong. Each one can show where its answers came from, and says so plainly when it can’t.

Python · Java · JavaScript · FastAPI · PostgreSQL · React · Docker · scikit-learn

A number you can’t trace is a number you can’t use.

Claim with a source attached Claim I haven’t measured yet, left open on purpose

Every claim on this page is either something you can open and check, or marked in red as something I haven’t measured. Nothing gets quietly dropped for looking bad. That rule is the whole argument, and it applies to this page before it applies to anything I’ve built.

Selected work

Advising

Acadvo

An academic and career advisor for Canadian university students that edits your actual degree plan.

Most “AI advisor” products are a chat box with a system prompt. Acadvo has sixteen function-calling tools and a multi-turn execution loop: it reads your degree progress, adds courses to your plan, flags at-risk requirement buckets, and builds semester-by-semester schedules against your university’s real catalogue.

The hard part was never the model. It was the course data — prerequisites, exclusions and enrolment gates, pulled from four Canadian universities’ own public sources rather than from anything the model believes it knows.

The decision
A degree requirement is a rule: “6.00 credits in AP/HUMA, minus these exclusions.” Hundreds of courses can satisfy a single one. Enumerating them by hand doesn’t scale, and letting the model invent them is worse than useless.
What I chose
One AI run reads the university’s own requirements page, extracts the rules, and caches the result with its source URLs for every student after. Every satisfied requirement is shown next to the page it was read from, labelled as either university-stated or Acadvo-inferred. An adapter never fabricates a course code.
The trade-off I accepted
Coverage. Unresearched programs say “unresearched” instead of producing a plausible answer. That costs me users in the first week. It is also the only reason anyone should trust the output in the first year. The sources I decided not to use are documented, with the reason.
Forecasting

UFC Fight Predictor

A fight-outcome model that keeps an honest, public scoreboard of its own mistakes.

A three-model ensemble — logistic regression, random forest and histogram gradient boosting — trained on historical bout data from ufcstats.com. It predicts a winner with a calibrated probability, predicts the method of victory, and will run every bout on an upcoming card in one command. It scrapes its own dataset, pulls median moneylines from the books, and blends the market into its estimate when a line exists.

Anyone can report a good accuracy number. The interesting engineering is in making that number mean something.

The problem
Fight prediction is a leakage minefield. A fighter’s career statistics already include the fight you’re trying to predict. Train on that and you get a model that looks brilliant in testing and is worthless on Saturday night.
What I built
A chronological replay: features for any bout are computed only from what was known before that bout, and evaluation trains on the past and tests on recent fights the model has never seen. Separately, a ledger logs every pick before the event, locks it, and grades it afterwards against the real result — accuracy, log-loss, and the market’s performance on the same fights.
What it told me
Over a leakage-free chronological backtest of roughly 1,300 bouts, the model on its own picks 65.1% of winners at 0.6359 log-loss. The betting market picks 70.0% at 0.5846 on the same fights, so the book is the better predictor and I am not going to write it up as though it isn’t. Folding the model into the market gets to 0.5821 log-loss at 69.7% accuracy: a fractional gain in calibration, paid for with slightly fewer winners. Backtesting also found the model’s disagreements with the market were not historically profitable. Every one of those numbers is in the README. The point of building the ledger was to be able to believe it when it tells me something I didn’t want to hear, and this is that.
Accounting

Personal Finance Tracker

A Java budgeting tool, written to learn where object boundaries belong.

Income, expenses, budgets and category analysis, built as four separate layers: a model layer of plain data types, a storage layer that owns all session state, a service layer that computes over it, and a console app that does nothing but talk to the user. It carries category budgets with automatic over-budget alerts, month-scoped reporting, and a computed daily spending allowance.

Why it’s here
The smallest project on this page. The first version put the arithmetic inside the model classes. Splitting the analyser out from the data (one FinanceData instance, one FinanceAnalyzer operating on it) is where layering stopped being a diagram in a lecture slide and started being a constraint the code enforces.

About

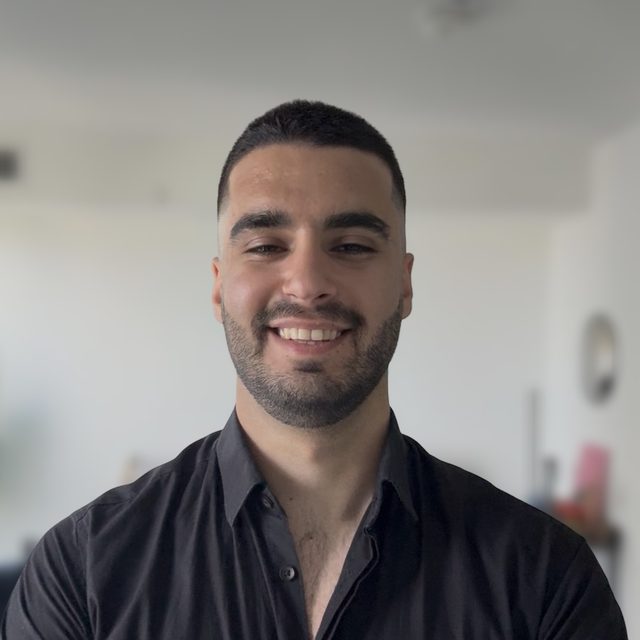
Arvin Zargaran, photographed straight-on against a plain wall.
Toronto · 2026

I grew up in Iran and came to Toronto on the International Scholarship of Distinction, a $37,500 entrance award, to read Computer Science at York’s Lassonde School of Engineering (Honours BSc). I want to spend the next few years writing production software, and then move toward technical product work without getting far enough from the code to stop being credible. I’m applying to both software engineering and technical product roles. English and Farsi, both fluent.

That second half is why I’m also taking the Bergeron Entrepreneurs in Science & Technology certificate, a cross-disciplinary program run across Lassonde, the Schulich School of Business and Osgoode Hall Law School. This year it is organizational behaviour, marketing, operations, accounting, finance and strategy, taught to engineers. I would rather learn what a business case looks like now than discover later that I can only argue about implementations.

I read financial news and market analysis for fun, which is why the two projects I care most about are really about the same question: how much should you believe a number somebody hands you? That’s the whole job in fintech, which is why I’m starting there.

  • 2026–Sales Specialist, Menswear — Over the Rainbow, Toronto. A high-volume retail floor, 20 hours a week alongside full-time studies.
  • 2025Office Administrator — Mabelle Dental, Yorkville. First point of contact for 20+ clients a day across a multilingual caseload; reconciled every transaction with zero discrepancies.
  • LanguagesPython, Java, JavaScript, SQL, HTML/CSS
  • BackendFastAPI, SQLAlchemy, PostgreSQL, Alembic, JWT auth
  • FrontendReact 19, Vite, Tailwind CSS
  • Data / MLpandas, scikit-learn, backtesting, model calibration
  • ToolingGit, Docker Compose, pytest, CI/CD, Linux

Contact

I’d rather talk about a hard data problem than an easy one. Email is the fastest way to reach me.